Tutorials Overview
How to self-host Open WebUI with Ollama using Docker Compose
Run a private ChatGPT-style chat app on your own VPS. This guide sets up Open WebUI and Ollama with Docker Compose, sizes CPU and GPU servers, adds HTTPS…
How to Self-Host SearXNG with Docker on a VPS
SearXNG is a free metasearch engine that sends your query to many search engines, merges the results and keeps no profile of you. To run your own self-hosted…
How to Self-Host OpenHands on a VPS: AI Coding Agent Setup
OpenHands is an open-source AI coding agent that edits code and runs shell commands in a workspace you control. To self-host it on a VPS, you run its…
How to Run gpt-oss-120b on a Single GPU VPS (96 GB VRAM)
gpt-oss-120b is OpenAI’s open-weight reasoning model, and it runs on a single GPU VPS with 96 GB of VRAM. Its mixture-of-experts weights ship natively in 4-bit MXFP4, so…
OpenClaw Use Cases: 25 Ways to Automate Work on Your Own VPS
OpenClaw is a self-hosted AI agent that runs on your own server and acts for you through chat apps, files and APIs. The best OpenClaw use cases are…
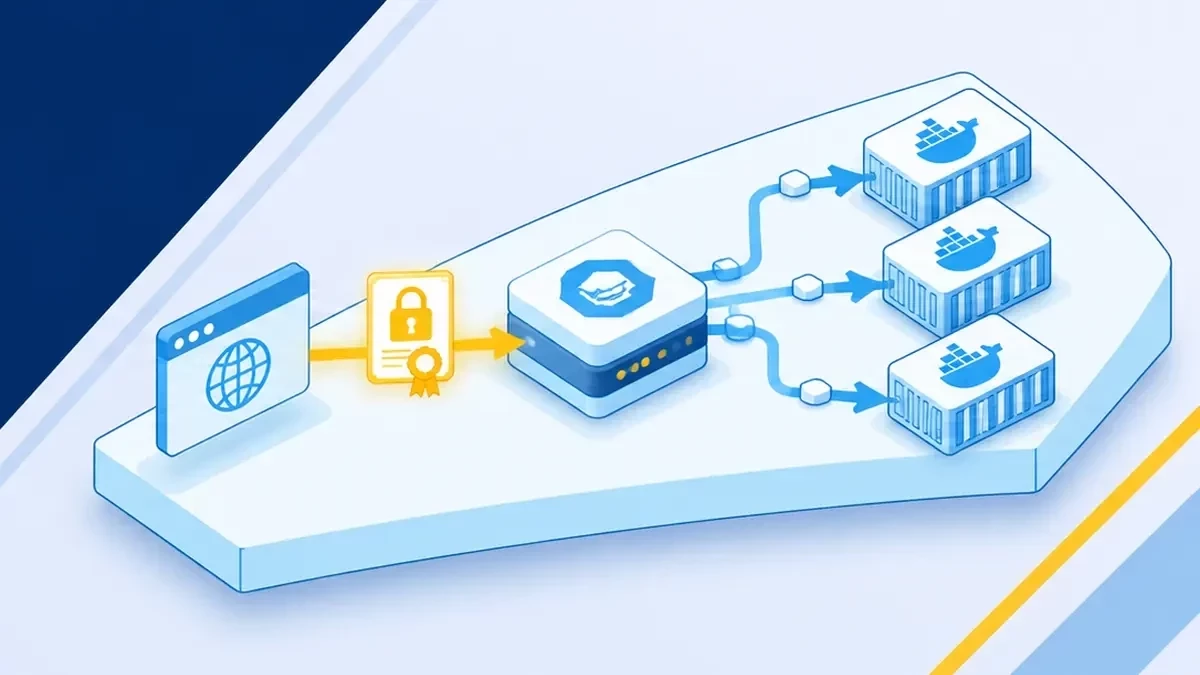
How to Install Nginx Proxy Manager with Docker on a VPS
Nginx Proxy Manager (NPM) is a web interface for running an Nginx reverse proxy with free Let’s Encrypt certificates. On a VPS you deploy it with a single…
How Much VRAM Do You Need to Run an LLM? Model Size Guide
How much VRAM you need for an LLM comes down to one calculation: parameters × bytes per weight, plus room for the KV cache and runtime overhead. That…
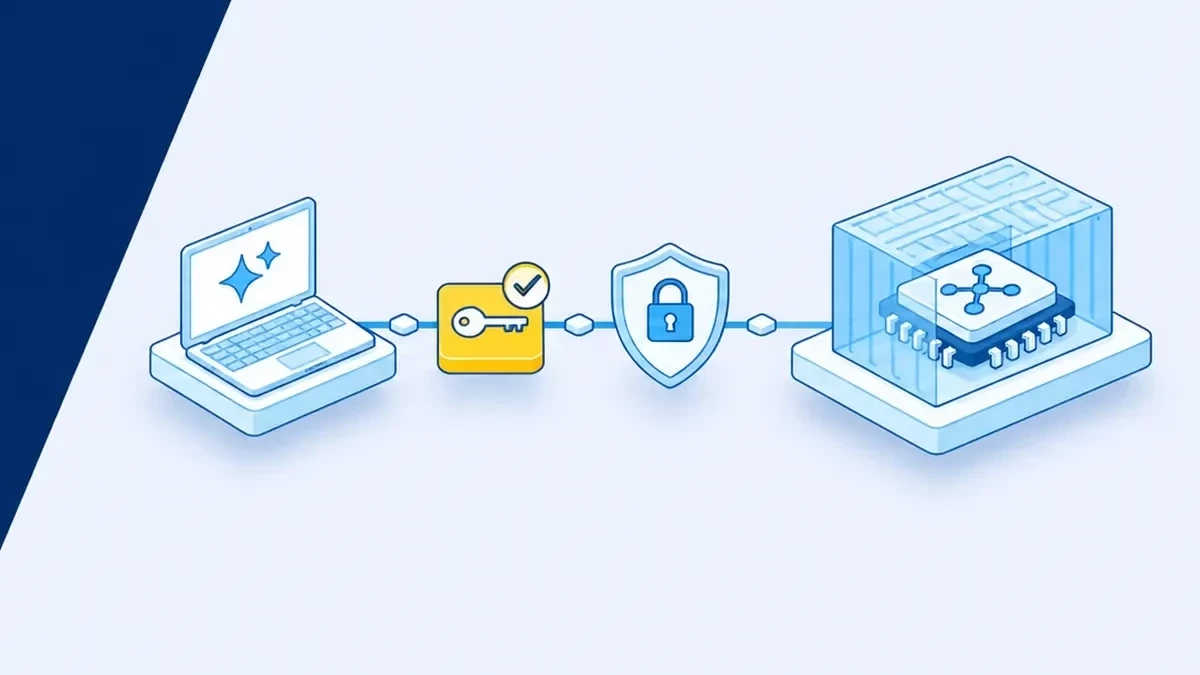
How to Host a Remote MCP Server on a VPS: Docker, HTTPS, Auth
A remote MCP server exposes tools to AI clients over HTTP instead of through a local process. To host one, you package the server in a container, run…
NVIDIA Container Toolkit on a GPU VPS: Drivers, CUDA and Docker
Set up a GPU VPS on Ubuntu: install NVIDIA drivers, add the NVIDIA Container Toolkit and run GPU containers in Docker. Verify with nvidia-smi.
How to Self-Host Piper TTS for Offline Voice Generation
Piper TTS is a free neural text-to-speech engine that runs on CPU alone. Learn how to install it on a VPS, download a voice, serve audio over HTTP,…
Llamafile on a VPS: Portable LLM Inference in One File
A llamafile bundles an LLM’s weights and the llama.cpp runtime into one executable. Learn how to run it on a VPS, expose an OpenAI-compatible API, secure port 8080,…
lldap or OpenLDAP? Picking a Self-Hosted LDAP Server
lldap and OpenLDAP solve the same problem very differently — here’s how to decide which one fits your setup.
Deploying Text Generation WebUI on a GPU VPS
Deploy Text Generation WebUI on a Contabo GPU VPS: clone the repository, load a model, and reach the browser interface over an SSH tunnel. You can also enable…
Setting Up lldap for Centralized VPS Authentication
lldap gives self-hosters a lightweight LDAP server without the usual complexity — here’s how to set it up on a VPS.
SGLang vs vLLM: Which Inference Engine Fits Your GPU VPS?
SGLang vs vLLM compared for self-hosted LLM inference — how they differ and which fits your workload on a GPU VPS.
Self-hosting Boop: a tiny notification inbox for developers
Boop is a self-hosted notification inbox that pushes events from your apps to your iPhone. This guide covers deploying it on a VPS with Docker, connecting Apple push…
Wan 2.2 Video Generation with ComfyUI: A GPU VPS Setup Guide
A step-by-step guide to running Wan 2.2 video generation in ComfyUI on a GPU VPS, from installing ComfyUI and downloading the model files to loading the native workflow…
Stop Paying for SaaS: A Self-Hosting Starter Roadmap
Start by auditing what you’re actually paying for, then replace one tool at a time — not everything at once. The order that works: set up your server…
Running KoboldCpp for local LLM inference on a VPS
KoboldCpp turns a VPS into a private LLM server with a web interface and an API. This guide covers what the tool is used for, how to deploy…
Self-Hosting SGLang: Fast LLM Inference on a GPU VPS
Deploy SGLang for fast, self-hosted LLM inference on a GPU VPS — what it is, how it installs, and when it’s the right choice.